SNAPAI Releases New Multimodal Model: What to Know
SNAPAI Releases New Multimodal Model: What to Know
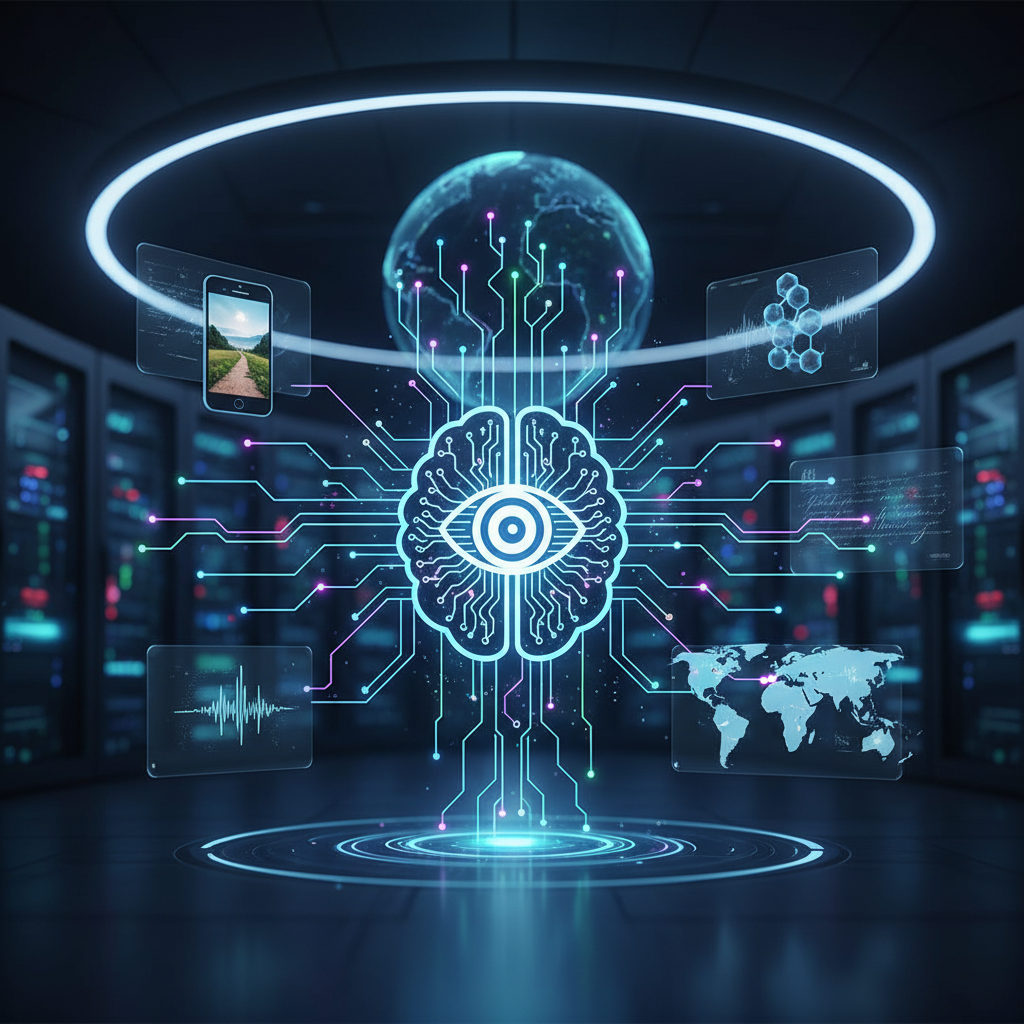
The AI lab SNAPAI has just released a new multimodal model that promises stronger image-and-text understanding, lower latency, and improved cross-modal reasoning. This article walks through the model’s core capabilities, performance signals, practical use cases, and what developers and product teams should consider before adopting it.
What is this multimodal model?
Put simply, SNAPAI’s latest model is designed to accept and reason over multiple input types—photos, diagrams, screenshots, and natural language. It bridges visual perception and language understanding so a single system can answer questions about images, summarize visual content, and fuse textual context with visual cues.
Core capabilities
- Image captioning and rich description generation.
- Visual question answering with multi-step reasoning.
- Cross-modal retrieval: find images from text and vice versa.
- Multimodal composition: generate text that references specific regions of an image.
Architecture highlights
The system combines a convolution-free vision encoder with a transformer-based multimodal decoder. That design reduces modality-specific engineering while allowing the model to learn joint representations. SNAPAI emphasized lower inference latency and modular checkpoints so teams can select the trade-off between speed and capability suitable for their applications.
Performance and benchmark signals
SNAPAI reported gains on a mix of internal and public evaluations. In their internal suites—labeled 6516, 6517, 6518, 6519—the model showed consistent improvements in cross-modal retrieval and multi-step reasoning compared with the previous release. Those identifiers (6516, 6517, 6518, 6519) appear in the release notes to help teams reproduce and compare evaluation runs.
What those numbers mean for real use
Benchmarks are useful shorthand, but practical impact depends on your use case. Expect:
- Faster and more accurate image-to-text mapping for search and accessibility features.
- Improved handling of complex questions about images (e.g., “What changed between these two photos?”).
- Better end-user experience in interactive agents that mix screenshots, text, and photos.
Use cases and developer notes
This release targets a wide range of applications. Here are common scenarios where the model shines and some practical notes for teams:
Practical applications
- Accessibility: automatic alt-text and descriptive assistance for images on the web and in apps.
- Content production: generating image-aware copy, social media captions, and editorial summaries.
- Customer support: interpreting screenshots or photos sent by users to speed diagnosis and resolution.
- Search and discovery: improving relevance by combining visual signals with textual metadata.
Developer considerations
- Model size vs. latency: choose the checkpoint that matches your response-time targets.
- Fine-tuning: SNAPAI provides targeted fine-tuning recipes when you need domain-specific accuracy.
- Annotation quality: multimodal models remain sensitive to the alignment quality between images and captions—clean labels help a lot.
Privacy, safety, and deployment
With any powerful vision-language system, it’s important to think about misuse and privacy. SNAPAI’s release notes call out recommended guardrails: content filters, human review for high-stakes outputs, and options to disable or redact face recognition and sensitive attribute inference. Teams deploying the model in production should:
- Audit performance across demographic groups and image sources.
- Apply content moderation layers where outputs could influence decisions about people.
- Limit data retention for uploaded images and follow applicable privacy laws.
How to get started
SNAPAI typically provides multiple entry points: an API for hosted inference, downloadable checkpoints for on-prem or private-cloud use, and SDKs to accelerate integration. Start by running the smaller checkpoint in a sandbox, evaluate on your real inputs, then scale to larger models only when you need the extra capabilities.
Final thoughts
SNAPAI’s new multimodal model is a meaningful step forward in blending vision and language. Whether you’re building accessibility features, smarter search, or more helpful virtual assistants, it offers practical improvements. Pay attention to the benchmark tags—6516, 6517, 6518, 6519—when comparing results, and plan for privacy and safety as you integrate the technology.
Adopting a multimodal system is a journey: start small, validate on your data, and iterate. When used responsibly, these models can unlock richer, more intuitive user experiences across products.